
What Usability Testing Actually Measures
ISO 9241-11 defines usability as the extent to which specified users can achieve specified goals with effectiveness (did they succeed), efficiency (how much effort it took), and satisfaction (how it felt to do it). Usability testing is the method built to measure all three at once: hand a real task to a real person, watch what happens, and record where the design and the user's expectations pull apart.
That's different from a survey, which captures what people say they'd do, and different from analytics, which shows what people did without explaining why. A usability test captures both - the behaviour, and through the think-aloud protocol, the reasoning behind it.
Where Think-Aloud Comes From
Narrating your thoughts while working isn't a UX invention. Psychologists K. Anders Ericsson and Herbert Simon established concurrent verbal reporting as valid research data in their 1980 paper "Verbal Reports as Data." Clayton Lewis adapted the technique for interface evaluation at IBM in 1982, and Jakob Nielsen folded it into his "discount usability engineering" framework in the early 1990s - the lightweight version most teams still run today.
The 5-Step Process
- 1. Define what you need to learn: "Can new users complete checkout without help?" is testable. "Is the app good?" is not.
- 2. Recruit real users, not colleagues: screen for the behaviours and context that matter - prior product use, device type, relevant experience - not just demographics.
- 3. Write task-based scenarios: "Imagine you want to change your billing address - show me how you'd do that" produces real behaviour. "Can you find the settings button?" produces a scavenger hunt.
- 4. Run the session with think-aloud: stay quiet during tasks. If a participant goes silent, prompt with "what are you thinking right now?" - never "try clicking there."
- 5. Group findings by severity, not by order observed: a problem three of five users hit outranks one that tripped up a single outlier.
How Many Users Do You Actually Need?
Jakob Nielsen and Tom Landauer's 1993 model puts the number at five, based on a typical problem-discovery rate of 31% per participant - the math predicts five users surface roughly 85% of usability problems. It's the most cited number in UX research. It's also the most misapplied.
Laura Faulkner retested the claim in 2003: she ran 60 participants through one study, then drew 100 random samples of five from that pool and counted how many known problems each sample caught. The average did land near 85% - but individual samples of five ranged from 55% to 100%. Jan Spool and Will Schroeder found only 35% of known issues after five participants on a complex e-commerce site, because that product's real discovery rate was nowhere near 31%. Five is a reasonable default for a discount, iterative test. It is not a guarantee.
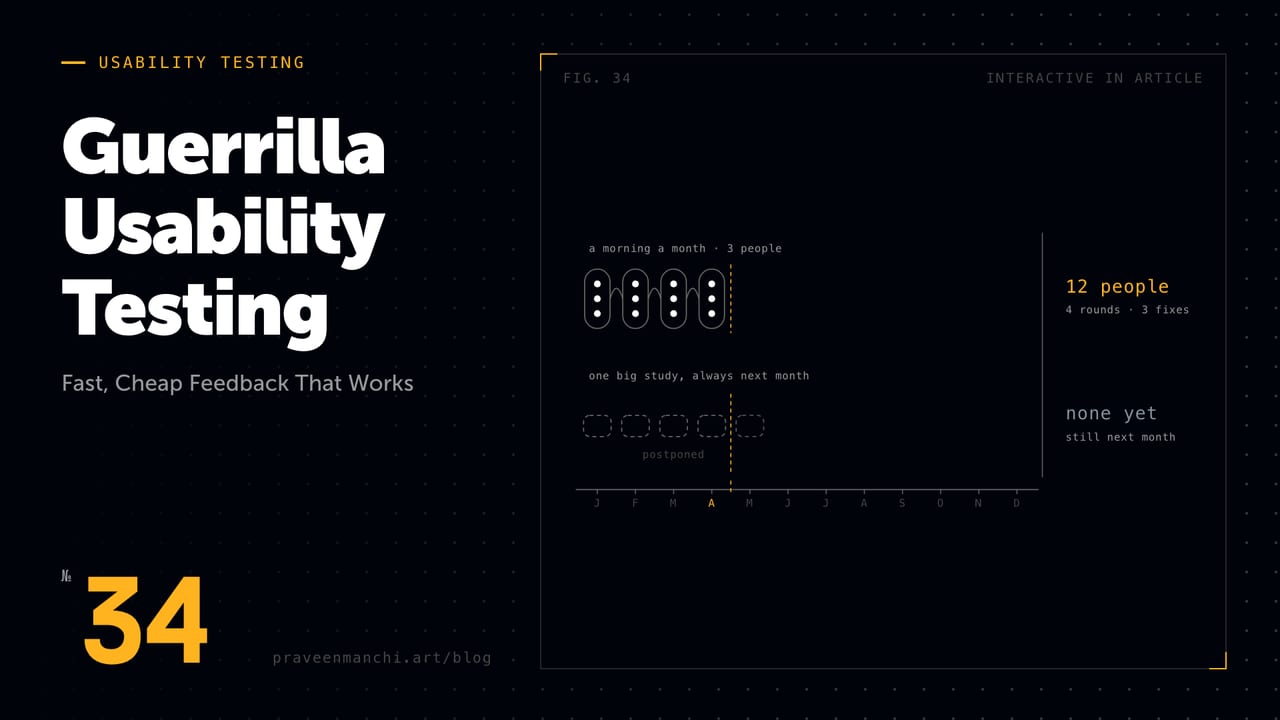
Nielsen's own recommendation accounts for this: run three small rounds of five rather than one round of fifteen. Fix what you find between rounds, then retest. Iteration compensates for what any single round of five will miss.
Moderated or Unmoderated?
Moderated: a researcher guides the session live, asking follow-up questions and adapting in real time - best for early prototypes and open-ended "why" questions. Unmoderated: participants complete tasks independently through a platform like Maze, Lyssna, or UserTesting, with no one watching live - faster, cheaper, and the only practical option once a study needs 30 or more participants. Most teams need both at different stages of a project.
Common Mistakes
- Leading questions ("Was that easy to find?") that prime the answer you want to hear.
- Treating one or two sessions as a pattern - outlier behaviour needs a second data point before you act on it.
- Testing after the build is locked, when findings can only inform the next release.
- Matching the wrong prototype fidelity to the question - paper for information architecture, high-fidelity for visual and copy decisions.
Key Takeaways
- ISO 9241-11's three components - effectiveness, efficiency, satisfaction - are what a usability test actually measures.
- Five users is a reasonable default, not a guarantee: Faulkner's real-world samples ranged from 55% to 100% coverage.
- Run several small rounds instead of one large one - iteration catches what any single round misses.
- Scenario-based tasks paired with think-aloud narration produce the richest data of any usability method.